Measured. Calculated. Explained.
The Element AI keeps measurement, tuning rules and language separate. Each part runs in the demo today; validation against blended perfumes is still to do.
- 01Lid photos
- 02Markers, warp, colour correction
- 03Oil / pH + confidence
- 04Scent ratings + routine tags
- 05Note graph + bounded rules
- 06Explanation + perfumer review
The photo is a measurement surface.
The browser reader uses js-aruco2 to find the printed markers, a four-point homography to straighten each zone, and the white and black patches to normalise colour. It compares the blot to its dry border and matches pH pads to the chart by CIELAB colour difference, returning confidence and quality flags. A vision model checks placement and glare; it never supplies the numbers.
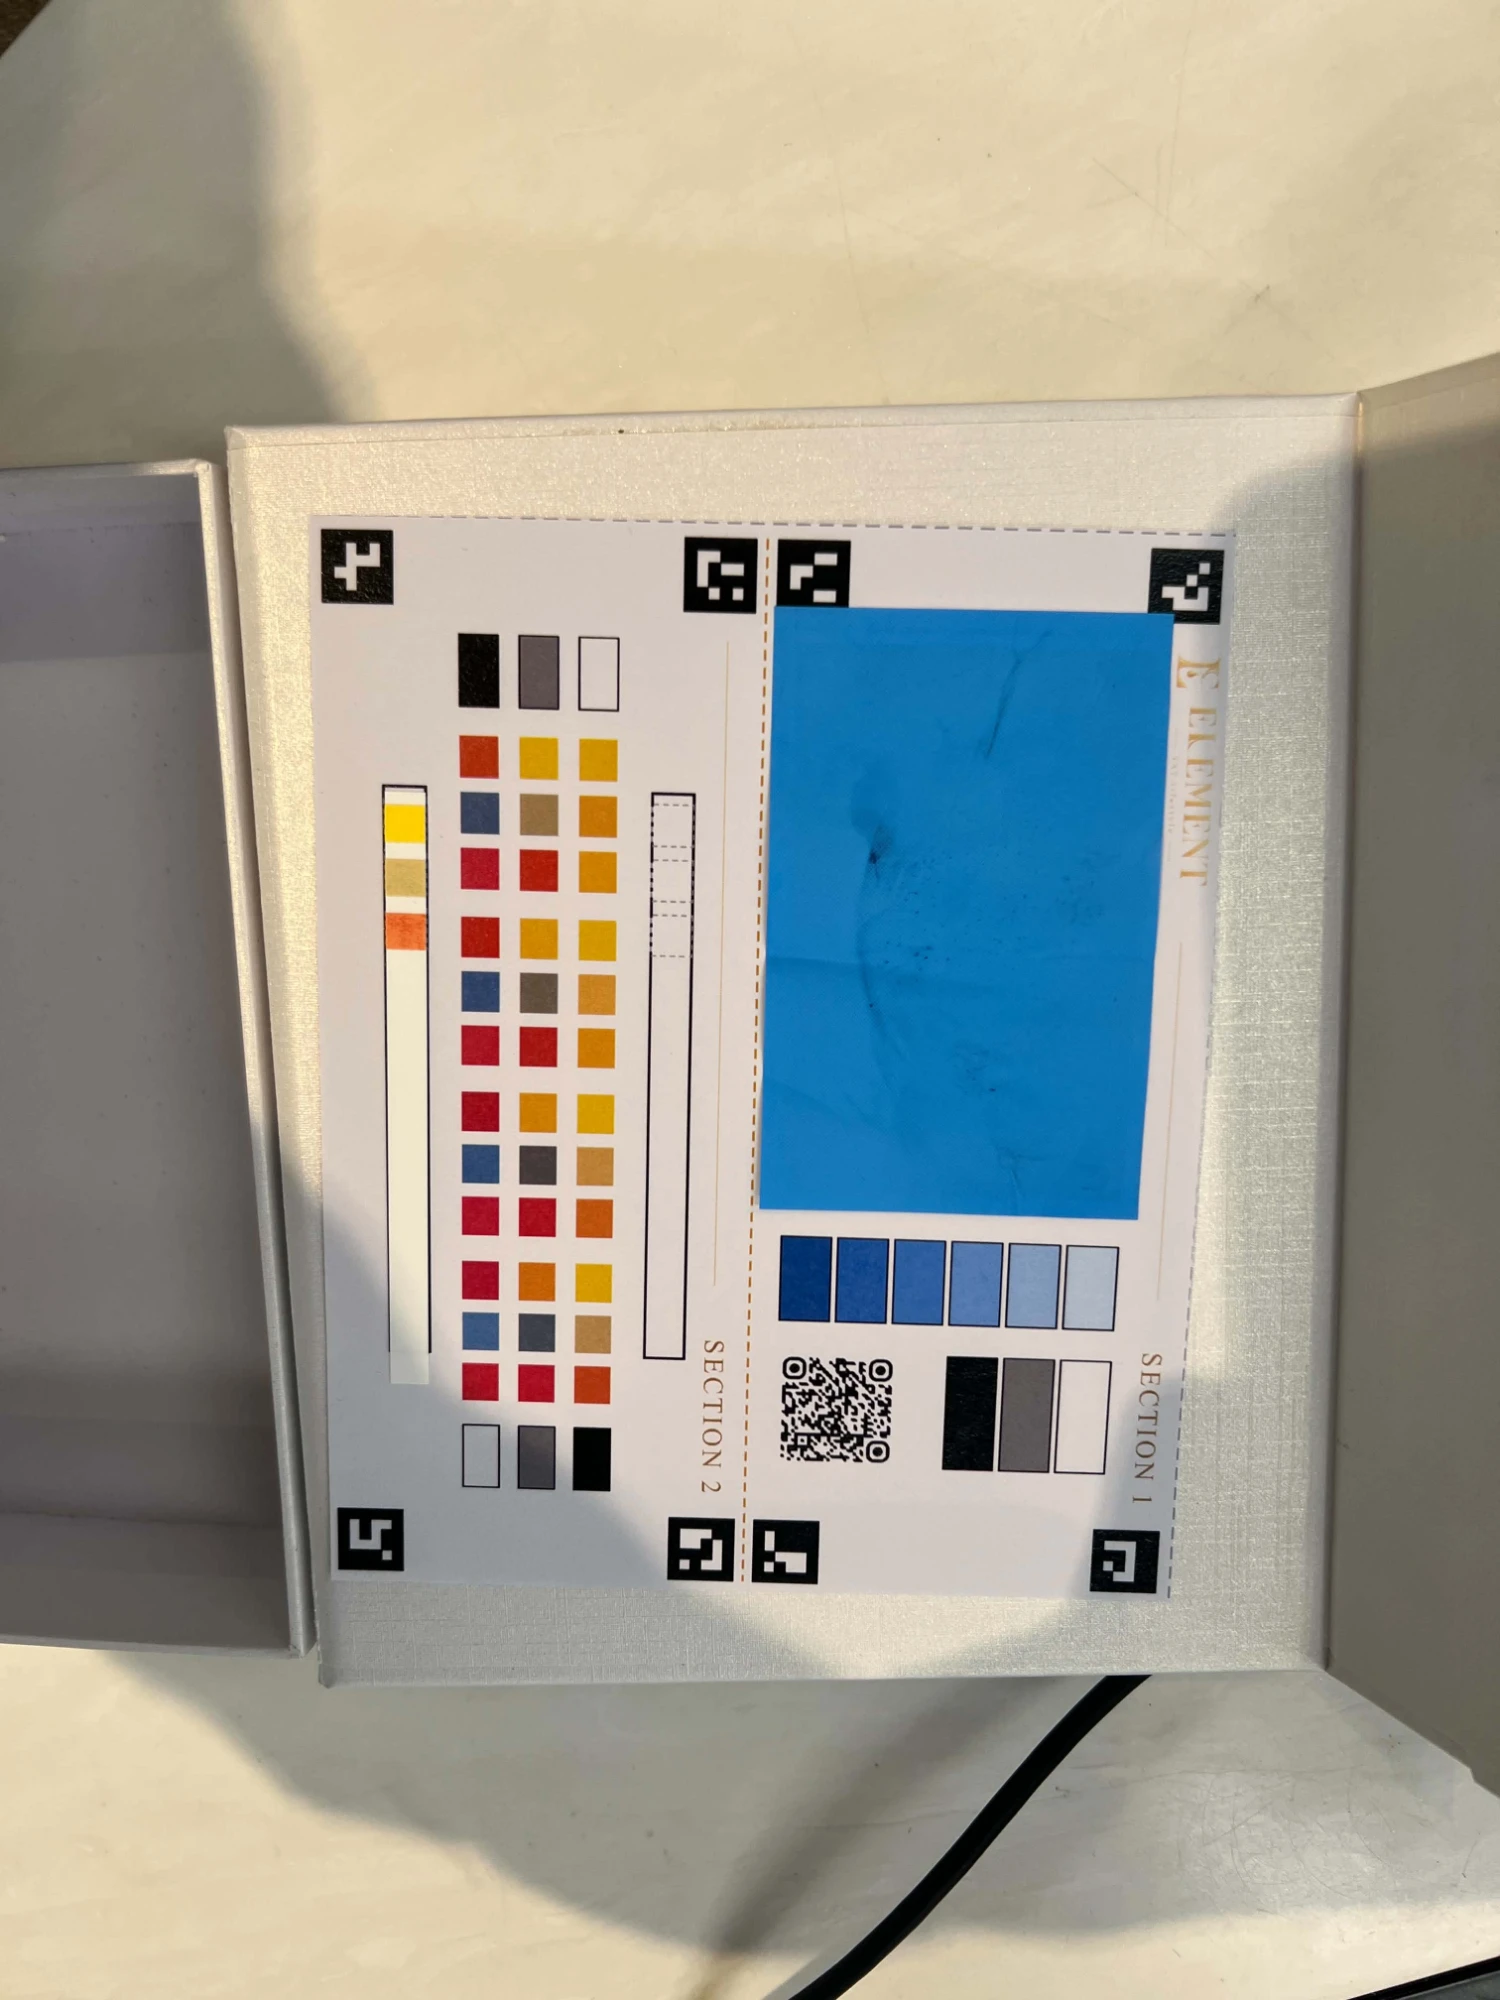
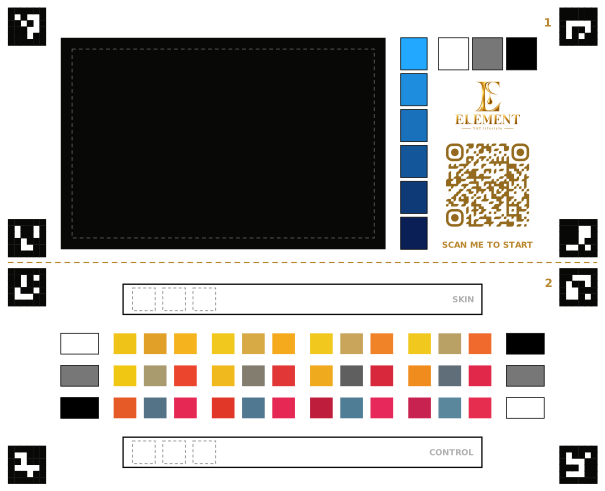
The capture uses an earlier board. A verified corrected output for the current board has not been supplied, so the target is a layout illustration, not an AI result. No reading accuracy is claimed.
Read the evidence [36] ↗A nose model, with its limits visible.
Keller & Vosshall 2016 collected ratings from 55 people for 480 molecules at two concentrations, under CC BY 4.0. Our model maps descriptors to scent families, clusters standardised person vectors with k-means and uses ridge regression for missing family ratings. Transfer from molecules to blended perfumes still needs testing.
Read the evidence [38] ↗Rules keep the base intact.
Tuning retrieves related notes and active traits. Each note moves by at most 20% of its weight or 6 points, whichever is larger, and at most two harmonious accents can be added before renormalisation. These are design bounds, not proof of an optimal formula. Oil informs tier balance, sensitivity informs concentration and routine informs projection. pH is recorded but never changes the formula.
Read the evidence [36] ↗Your scent, in three layers.
- OpeningThe first impression
- HeartThe fragrance's character
- Dry-downThe lasting trail
Small, bounded adjustmentsYour ratings + observations guide the suggestion.
AI explains. Perfumer review before blending.
The language model has a small job.
It selects a bank question or a short follow-up, extracts confirmed tags and explains computed changes. It cannot invent a measurement, diagnose, or add, remove or resize a formula change. Invalid or slow answers fall back to bank questions and template explanations.
A perfumer reviews every formula before mixing.
Read the evidence [36] ↗Designed for the phone and Cloudflare.
Photo measurement runs on the phone. The server calls Workers AI through AI Gateway, keeps sessions and readings in D1, lid photos in R2, and multilingual tags in Vectorize.
A perfumer reviews every formula before mixing.
Not a medical or diagnostic device.